
Approximate Aggregate Functions in BigQuery

Sometimes you don't need perfect, but just good enough. Take approximate aggregate functions in BigQuery, for example.
These are a type of aggregate functions that produce approximate results instead of exact ones but have the upside of typically requiring fewer resources for the computation.
When would I use one? This would be suitable where we can live with an uncertainty or small difference, especially for huge tables, during a preliminary check or data exploration.
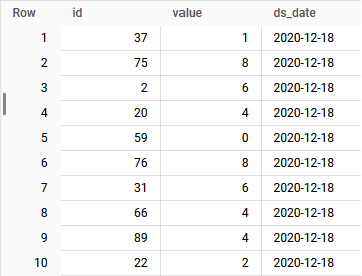
Let's look at a practical example. Suppose we have the following data:
APPROX_TOP_COUNT will compute the approx top N elements and their value counts
SELECT
    APPROX_TOP_COUNT(value, 5) AS top_value_counts
FROM `learning.data_source`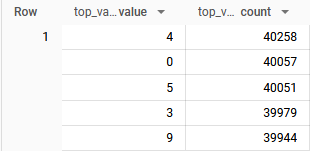
APPROX_COUNT_DISTINCT will compute the approx distinct count (also can be grouped)
SELECT
    APPROX_COUNT_DISTINCT(value) AS approx_distinct_value_count
FROM `learning.data_source`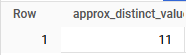
You can discover more approximate aggregate functions in the documentation.
Thanks for reading!
Enjoyed this? Here are some related articles you might find useful: