
De-duplicating with ROW_NUMBER vs ARRAY_AGG

What function do you use to explicitly de-duplicate in BigQuery?
I normally use ROW_NUMBER(), but I've recently encountered a really interesting blog post suggesting ARRAY_AGG might be more performant for the task.
The explanation given is that the ORDER BY is allowed to drop everything except the top record on each GROUP BY, making ARRAY_AGG more efficient.
Sure enough, I did give it a try on some sample data.
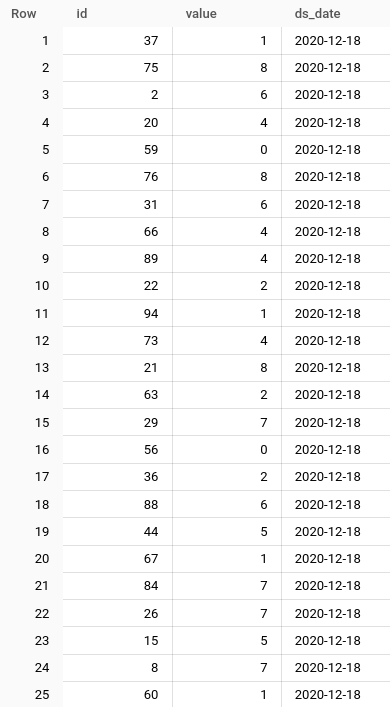
In the below example, we'd like to pick the latest date available per id. The ROW_NUMBER example is pretty straightforward - we partition by id and order by ds_date decreasingly, then use the QUALIFY clause to keep only the record we want.
SELECT * FROM `learning.data_source`

QUALIFY ROW_NUMBER() OVER (PARTITION BY id ORDER BY ds_date DESC ) = 1
The ARRAY_AGG example, while looking a bit more intimidating, does the same thing.
WITH last_events AS (

SELECT AS VALUE ARRAY_AGG(t ORDER BY t.ds_date DESC LIMIT 1)[OFFSET(0)]

FROM `learning.data_source` t

GROUP BY id
)

SELECT * FROM last_events
It turns out that the recommendation holds - slot time for the ARRAY_AGG version was only 40% of the ROW_NUMBER. Another day, another lesson learned.
Enjoyed this? Here are some related articles you might find useful: