
Loading data from Google Cloud Storage into BigQuery using Cloud Workflows

Google Cloud Workflows is a serverless orchestration platform that allows us to combine services into repeatable and observable sets of actions, connecting typically other GCP services. These are called, you guessed it, workflows.
While working as a Data Engineer and extensively using Apache Airflow (and its GCP implementation called Composer), I was a little skeptical in the beginning about what it is offering but came to appreciate its straightforwardness and simplicity.
In this quick exercise, we’re going to illustrate a simple use case — loading a CSV file from Google Cloud Storage into BigQuery.
Preparation work
Let’s set up the appropriate accounts and permissions. For this job, we’ve created a service account and assigned it the role “Big Query Job User”

Project roles for our service account
We’re also granted permission to the same service account to the Google Cloud Storage bucket from where we intend to load data from.

Bucket permissions for the service account
Next, we need to create a destination BigQuery dataset and provide the service account “Big Query Data Editor” role on it. Note that the dataset needs to be in the same GCP region (or multi-region) as the bucket load our data into.

BigQuery Destination dataset permissions
Now, let’s have a look at our file — a regular comma-delimited CSV, with the first row being the header row.
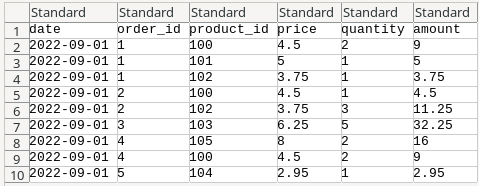
date,order_id,product_id,price,quantity,amount
2022-09-01,1,100,4.5,2,9
2022-09-01,1,101,5,1,5
2022-09-01,1,102,3.75,1,3.75
2022-09-01,2,100,4.5,1,4.5
2022-09-01,2,102,3.75,3,11.25
2022-09-01,3,103,6.25,5,32.25
2022-09-01,4,105,8,2,16
2022-09-01,4,100,4.5,2,9
2022-09-01,5,104,2.95,1,2.95
By our legend, this file follows the below naming convention, with the first part being the date of the sale.

All good, now let’s get to the workflow itself.
Creating the workflow

In the dialog box we are presented, we give our workflow a name, pick the region and a service account (same as the one that we granted permissions above) to run the workflow under.

If, let’s say, we’d like to read the file every day, that is — run the workflow on a particular schedule, we can create a Cloud Scheduler Trigger. This would automatically run the workflows at the given cadence.
Note that the project-level role “Workflows Invoker” needs to be attached to the service account triggering the Workflow.

A workflow with a trigger would look as follows

Creating the steps
We now have the Workflow development window, where we can write the definition for our workflow in YAML-esque syntax. If you aren’t familiar with Workflow syntax, a good place to start is the Workflows tutorials page. Also, note the pane on the right side, illustrating our control flow
# This is a sample workflow to test or replace with your source code.
#
# This workflow passes the current day of the week to the Wikipedia API and
# returns a list of related Wikipedia articles.
# The current day of the week (in GMT) is retrieved from a Cloud Function
# unless you input your own search term (for example, {"searchTerm": "Monday"}).
main:
    params: [input]
    steps:
    - checkSearchTermInInput:
        switch:
            - condition: ${"searchTerm" in input}
              assign:
                - searchTerm: ${input.searchTerm}
              next: readWikipedia
    - getCurrentTime:
        call: http.get
        args:
            url: https://us-central1-workflowsample.cloudfunctions.net/datetime
        result: currentDateTime
    - setFromCallResult:
        assign:
            - searchTerm: ${currentDateTime.body.dayOfTheWeek}
    - readWikipedia:
        call: http.get
        args:
            url: https://en.wikipedia.org/w/api.php
            query:
                action: opensearch
                search: ${searchTerm}
        result: wikiResult
    - returnOutput:
            return: ${wikiResult.body[1]}
We now need the build the workflow logic. For this exercise, we’ll need to check the configuration options we can set up for the BigQuery job, documented at the following link
The easiest approach is to try to load data while using the schema auto-detect. Note the autodetect: true part in the load configuration.
The below code will:
-
declare a resultsList List where we would accumulate job results
-
create a BigQuery insert job with a set of provided arguments
-
append the end state of the insert job to the list previously created
-
print the list of job statuses us upon workflow completion
- declare:
    assign:
        - resultsList: []

- insertAutoDetect:
    call: googleapis.bigquery.v2.jobs.insert
    args:
        projectId: "YOUR-PROJECT-ID-HERE"
        body:
            configuration:
                load:
                    autodetect: true
                    destinationTable:
                        datasetId: "sales_data"
                        projectId: "YOUR-PROJECT-ID-HERE"
                        tableId: "sales_autodetect"
                    fieldDelimiter: ","
                    skipLeadingRows: 1
                    sourceFormat: "csv"
                    sourceUris: "gs://YOUR-BUCKET-NAME-HERE/20220901_orders.csv"
                    writeDisposition: "WRITE_TRUNCATE"
    result: insertAutoDetectResult
- appendInsertAutoDetectResult:
    assign:
      - resultsList: '${list.concat(resultsList, insertAutoDetectResult.status.state + " for " + insertAutoDetectResult.configuration.load.destinationTable.tableId)}'

- returnOutput:
return: ${resultsList}BigQuery has auto-detected the column types and loaded the data.

If we were to choose to provide the schema to the job, we can do the following:
- declare:
    assign:
        - resultsList: []

- insertWithProvidedSchema:
    call: googleapis.bigquery.v2.jobs.insert
    args:
        projectId: "YOUR-PROJECT-ID-HERE"
        body:
            configuration:
                load:
                    destinationTable:
                        datasetId: "sales_data"
                        projectId: "YOUR-PROJECT-ID-HERE"
                        tableId: "sales_provided_schema"
                    fieldDelimiter: ","
                    schema:
                        fields:
                            - name: "date"
                              type: "DATE"
                            - name: "order_id"
                              type: "INTEGER"
                            - name: "product_id"
                              type: "INTEGER"
                            - name: "price"
                              type: "NUMERIC"
                            - name: "quantity"
                              type: "INTEGER"
                            - name: "amount"
                              type: "NUMERIC"
                    skipLeadingRows: 1
                    sourceFormat: "csv"
                    sourceUris: "gs://YOUR-BUCKET-NAME-HERE/20220902_orders.csv"
                    writeDisposition: "WRITE_TRUNCATE"
    result: insertWithProvidedSchemaResult

- appendinsertWithProvidedSchemaResult:
    assign:
- resultsList: '${list.concat(resultsList, insertWithProvidedSchemaResult.status.state + " for " + insertWithProvidedSchemaResult.configuration.load.destinationTable.tableId)}'Upon execution, this produces the following result.

What if we have a slightly more advanced use case, and would like to read hundreds of files, which can be quite big, into a partitioned table? The code could look something like the one below.
Notice the following:
-
timePartitioning by “DAY” based on field date
-
the sourceUris now has a wildcard “*” to catch all the files ending in “_orders.csv”.
- declare:
    assign:
        - resultsList: []

- insertIntoPartitioned:
    call: googleapis.bigquery.v2.jobs.insert
    args:
        projectId: "YOUR-PROJECT-HERE"
        body:
            configuration:
                load:
                    destinationTable:
                        datasetId: "sales_data"
                        projectId: "YOUR-PROJECT-HERE"
                        tableId: "sales"
                    fieldDelimiter: ","
                    timePartitioning:
                      field: "date"
                      type: "DAY"
                    schema:
                        fields:
                            - name: "date"
                              type: "DATE"
                            - name: "order_id"
                              type: "INTEGER"
                            - name: "product_id"
                              type: "INTEGER"
                            - name: "price"
                              type: "NUMERIC"
                            - name: "quantity"
                              type: "INTEGER"
                            - name: "amount"
                              type: "NUMERIC"
                    skipLeadingRows: 1
                    sourceFormat: "csv"
                    sourceUris: "gs://YOUR-BUCKET-NAME-HERE/*_orders.csv"
                    writeDisposition: "WRITE_TRUNCATE"
    result: insertIntoPartitionedResult
- appendInsertIntoPartitionedResult:
    assign:
- resultsList: '${list.concat(resultsList, insertIntoPartitionedResult.status.state + " for " + insertIntoPartitionedResult.configuration.load.destinationTable.tableId)}'We now have a partitioned table

SELECT

  date AS SalesDate,
  count(distinct order_id) AS CountOrders,
  sum(Amount) as TotalAmount

FROM
  `**REDACTED**.sales_data.sales`

GROUP BY
  date
Conclusion
As we have seen in this exercise, loading data from Google Cloud Storage into BigQuery using Cloud Workflows is quite straightforward and allows us to leverage the BQ API to build repeatable and low-overhead data pipelines in Google Cloud. Thanks for reading!
Enjoyed this? Here are some related articles you might find useful: